 LinkedIn


Self-Hosted Inference: The Good, Bad, and Ugly
Thursday, December 17, 2026
9 am PT | 12 pm ET | 6 pm CET
As AI token spend becomes the largest line item on the AI bill, more companies are asking whether to run their own models on their own GPUs. Private AI promises control over cost, data, and latency. But who runs it? The platform team, of course. Inference is just another Kubernetes service… right? Right??
Red Hat Senior Software Engineer Alexa Griffith (llm-d) sits down with Buoyant's Richard Collins ([K]inference) to talk honestly about what it takes to move from hosted APIs like Anthropic and OpenAI and build an in-house inference platform on Kubernetes. They'll discuss when moving your inference to self-hosted makes financial sense, and what numbers are important to crunch. Then, what self-hosting actually looks like, from convincing SRE teams to the long-term cost of adoption and maintenance. Most importantly for those in regulated environments, how self-hosted inference switches the conversation for staying within regulation and keeping everyone happy.
Bring your questions. We'll bring our answers.
What to expect
Runbook LIVE is where Buoyant talks with project maintainers, engineers running open source in production, or shows off new feature demos. Every month, depending on what's worth talking about, we host a fireside chat with a guest, a live demo, an AMA, or a war story from someone's real incident. There are no slides or fixed curriculum. It's a 30-minute live conversation, and you help shape it: drop in questions, vote in polls, and steer where the discussion goes. Whatever we cover, you'll walk away with something you can actually use, not just something you sat through.
What to expect
Runbook LIVE is where Buoyant talks with project maintainers, engineers running open source in production, or shows off new feature demos. Every month, depending on what's worth talking about, we host a fireside chat with a guest, a live demo, an AMA, or a war story from someone's real incident. There are no slides or fixed curriculum. It's a 30-minute live conversation, and you help shape it: drop in questions, vote in polls, and steer where the discussion goes. Whatever we cover, you'll walk away with something you can actually use, not just something you sat through.
Speakers

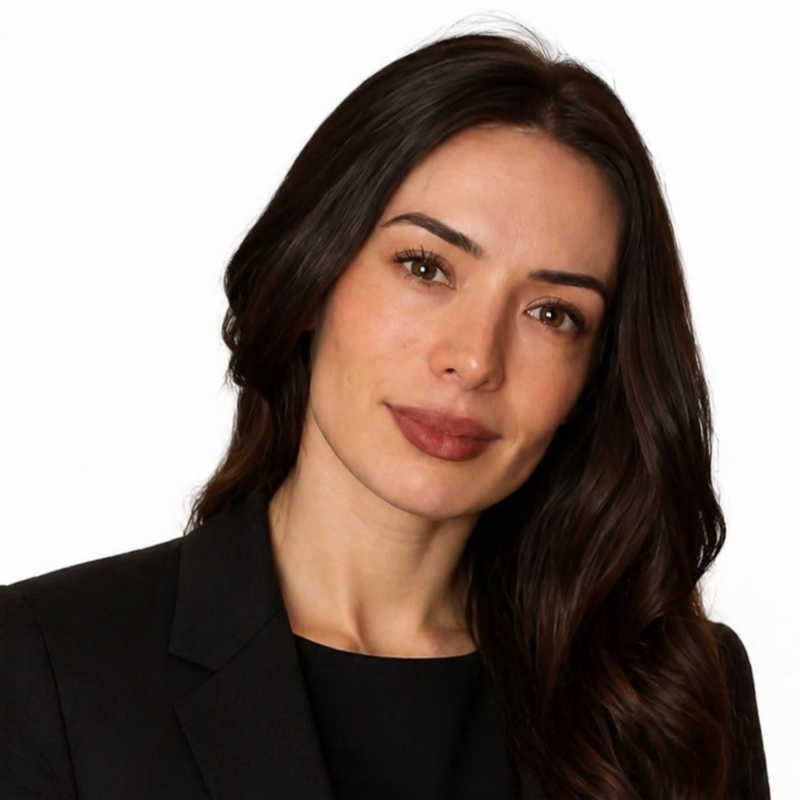
Alexa Griffith
|
Sr. Principal SWE; Red Hat
Senior Principal Software Engineer and Forward Deployed Engineer at Red Hat, working on AI inference infrastructure. I host Alexa’s Input (AI) and co-host Attention Deficit with Taylor Dolezal. I also share technical writing, talks, and learning resources about distributed systems and cloud-native AI.
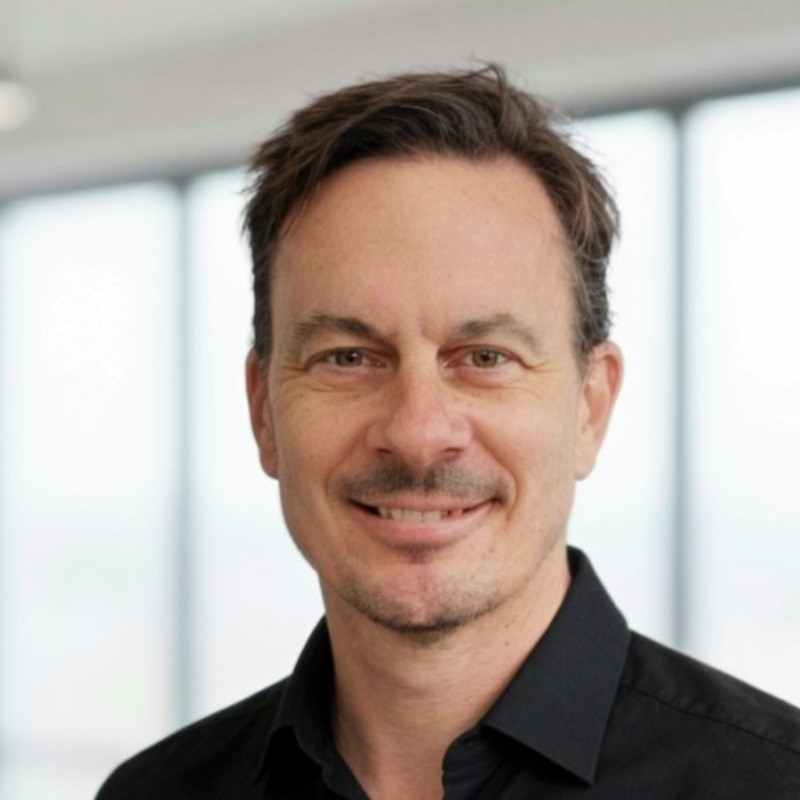
Richard Collins
|
Product Marketing Director, [K]inference
Richard Collins is an experienced cloud native technology and product leader with over 15 years of experience working across open source technologies spanning cloud, IoT, and mobile. At Jetstack, he worked closely with the team behind cert-manager, the widely adopted CNCF project that automates TLS certificate management in Kubernetes.